Wan 2.2 Cinematic I2V + InfiniteTalk - 24GB-Tuned ComfyUI Workflow Pack (720p)
A downloadable game
Not another repackaged "example workflow". These are the settings that actually rendered, on a 24GB laptop GPU, with the reasoning written next to each number.
WHAT YOU GET
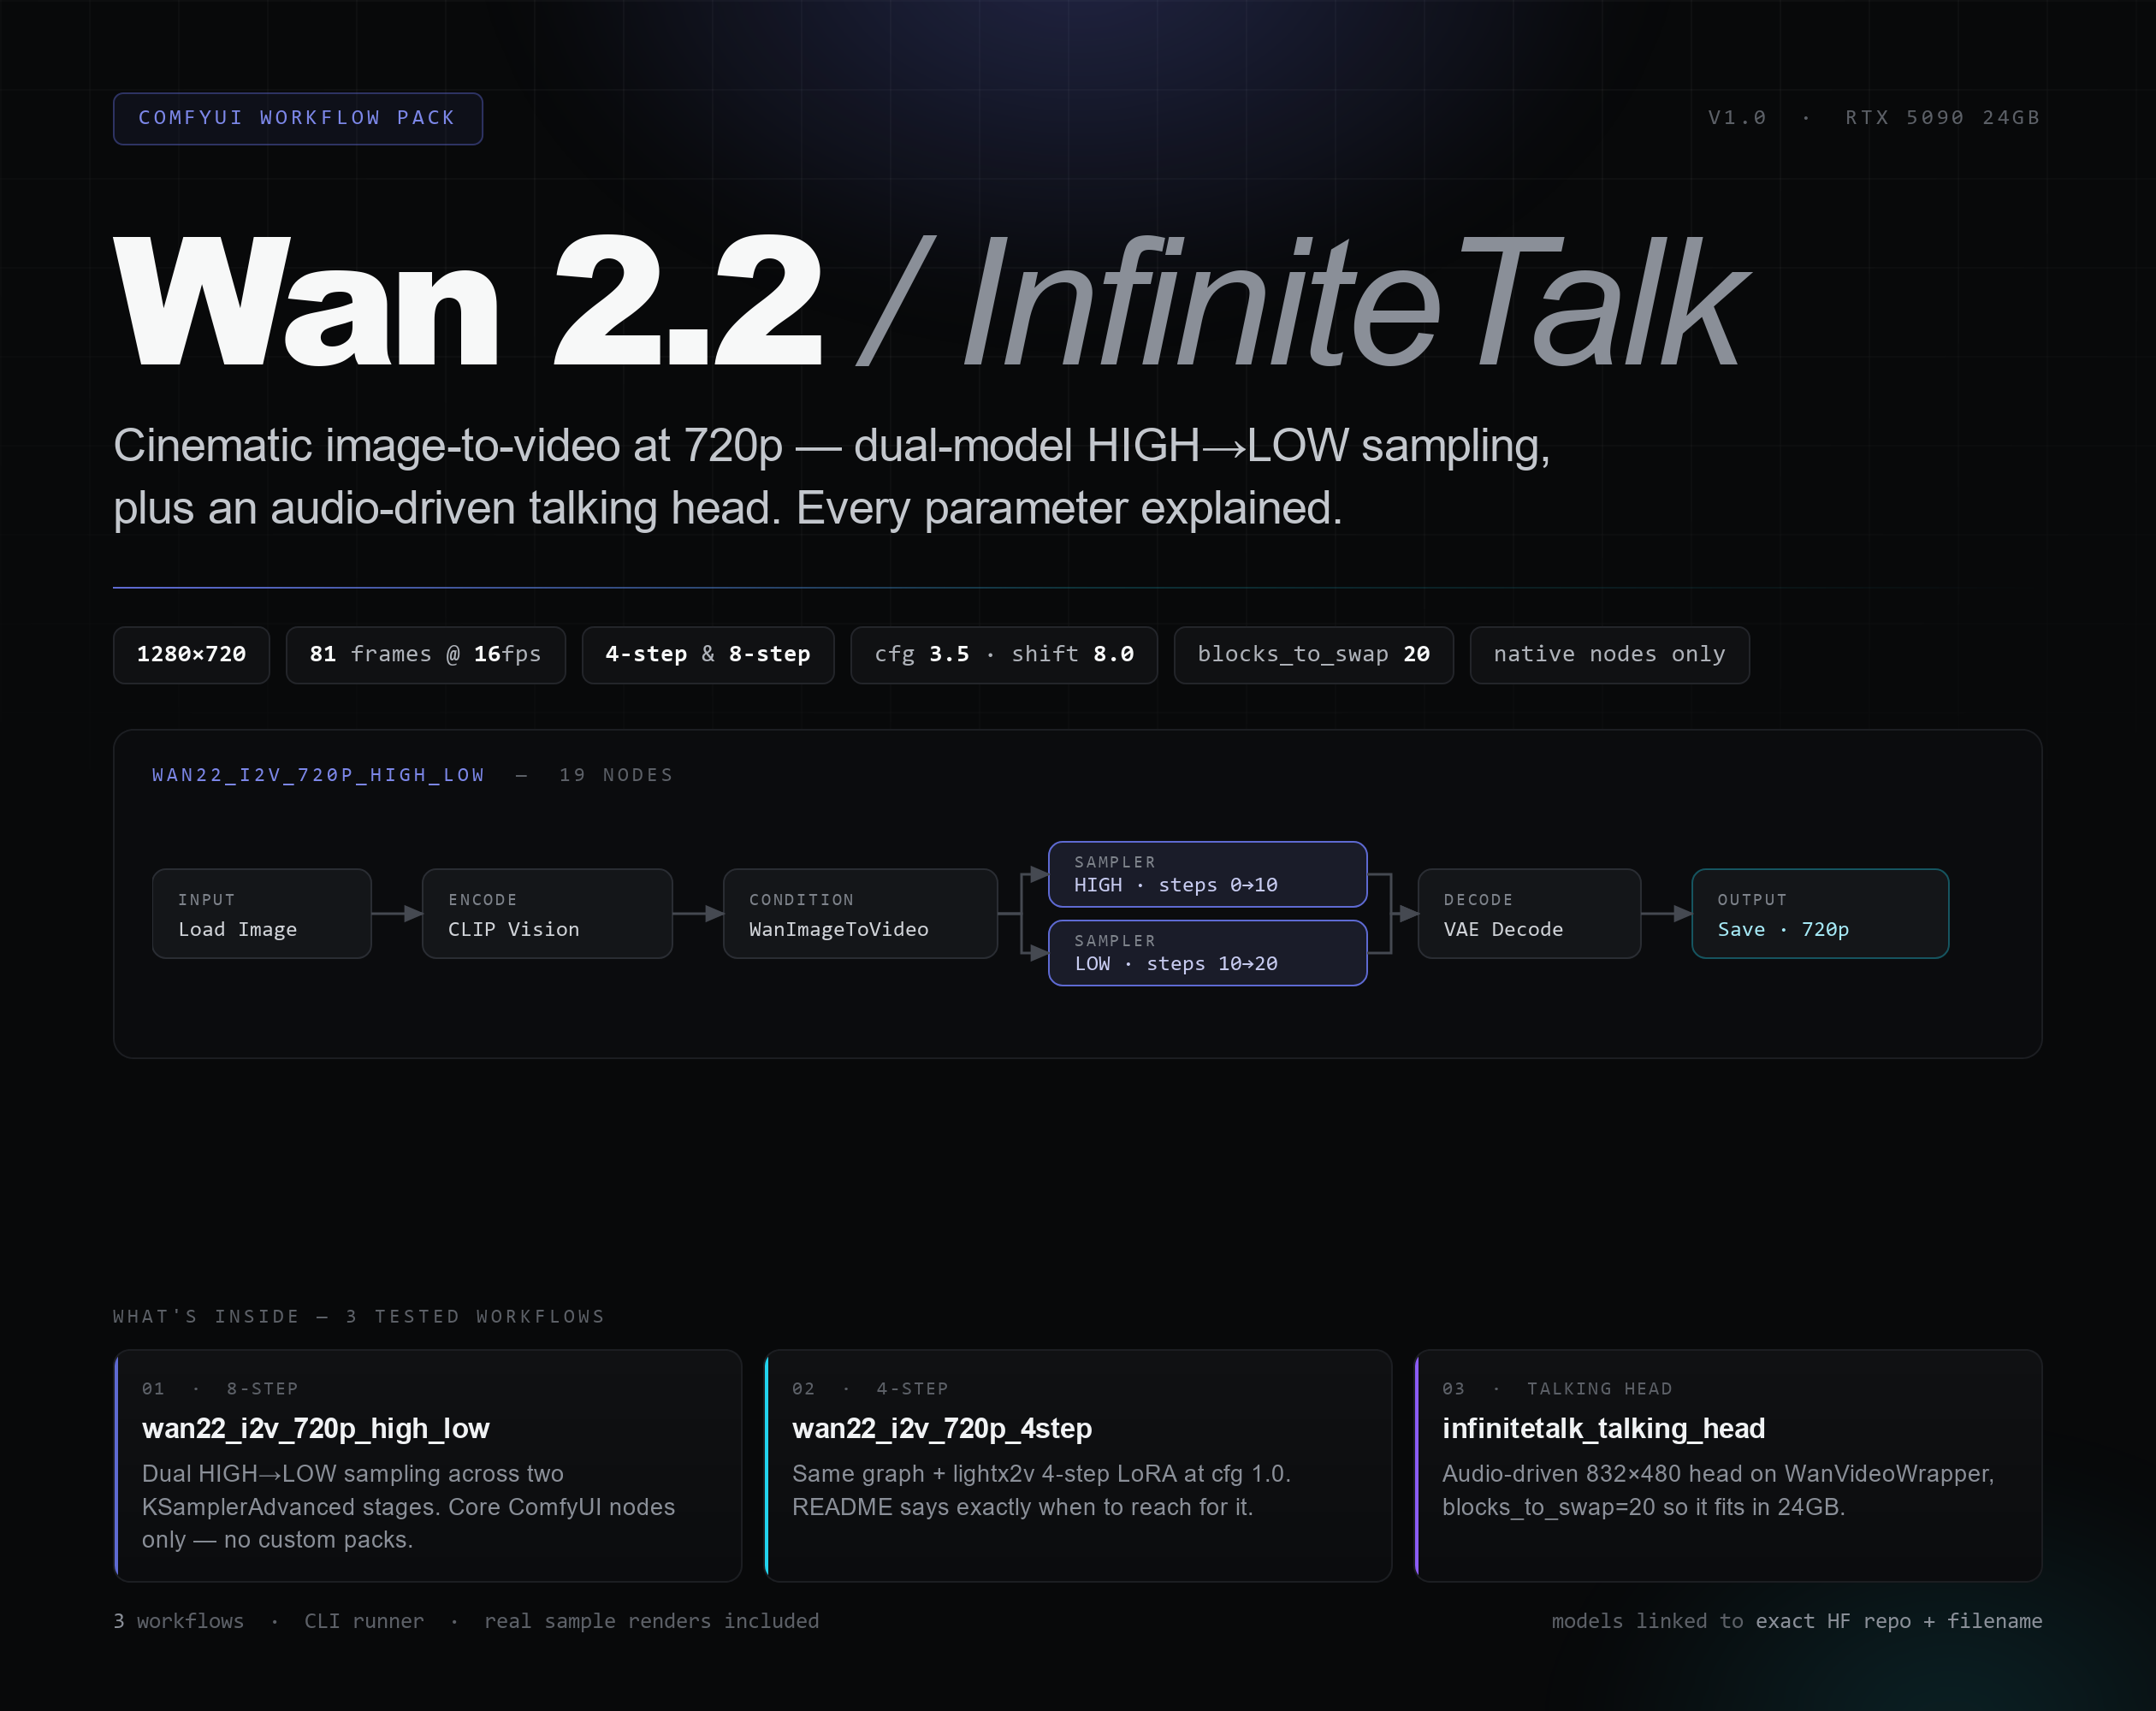
- wan22_i2v_720p_high_low Wan 2.2 I2V, 1280x720, 81 frames @16fps (5.06s), dual-model HIGH->LOW sampling across two KSamplerAdvanced stages. Core ComfyUI nodes only - no custom node packs.
- wan22_i2v_720p_4step_lightning Same graph + the lightx2v 4-step LoRA at cfg 1.0 (measured slower than the 8-step graph on a 24GB card - the README says why, and says when to reach for it)
- infinitetalk_talking_head_480p Audio-driven talking head (832x480) on ComfyUI-WanVideoWrapper, blocks_to_swap=20 so it fits 24GB.
- scripts/run_workflow.py Queue any workflow from the CLI, no UI required.
- samples/ Real renders from each workflow - compare the 4-step and 8-step outputs yourself before you buy into either.
- README with the exact, verified download source for every model file.
WHY THE PARAMETERS ARE THESE PARAMETERS
81 frames is 4n+1, which is what Wan's temporal packing requires. The HIGH->LOW handoff splits at exactly half the step budget because the LOW model is trained on low-noise steps. cfg 3.5 is where motion stops crawling on I2V. shift 8.0 on ModelSamplingSD3. The README explains each one and what to change when you want a different look - including what to touch first if you're not on 24GB.
MEASURED ON THE MACHINE THIS WAS TUNED ON (RTX 5090 Laptop, 24GB, ComfyUI 0.30.x, PyTorch 2.11 cu128)
- 720p 8-step HIGH->LOW: 1135s for 81 frames (5.06s of video at 16fps)
- 720p 4-step Lightning LoRA: 1731s - yes, slower than 8-step on this card. VRAM is saturated, so the sampler is memory-bound; fewer steps does not mean faster here. The README explains when the 4-step graph is still the right pick.
- InfiniteTalk 480p: 1080s for a 15.72s talking-head clip (windowed, frame_window_size=212)
REQUIREMENTS
- ComfyUI 0.30.x, PyTorch 2.11 (cu128 build used here)
- ~24GB VRAM for the 720p workflows (drop to 832x480 below that - README says how)
- sage attention recommended: python main.py --use-sage-attention --disable-smart-memory
- Models are NOT included (they're multi-GB and licensed separately); every one is listed with its exact Hugging Face repo and filename.
SUPPORT
Questions about a workflow? Ask on this page - I answer.
Digital download. No DRM, no license server, no phone-home.
Purchase
In order to download this game you must purchase it at or above the minimum price of $12 USD. You will get access to the following files:
Development log
Leave a comment
Log in with itch.io to leave a comment.